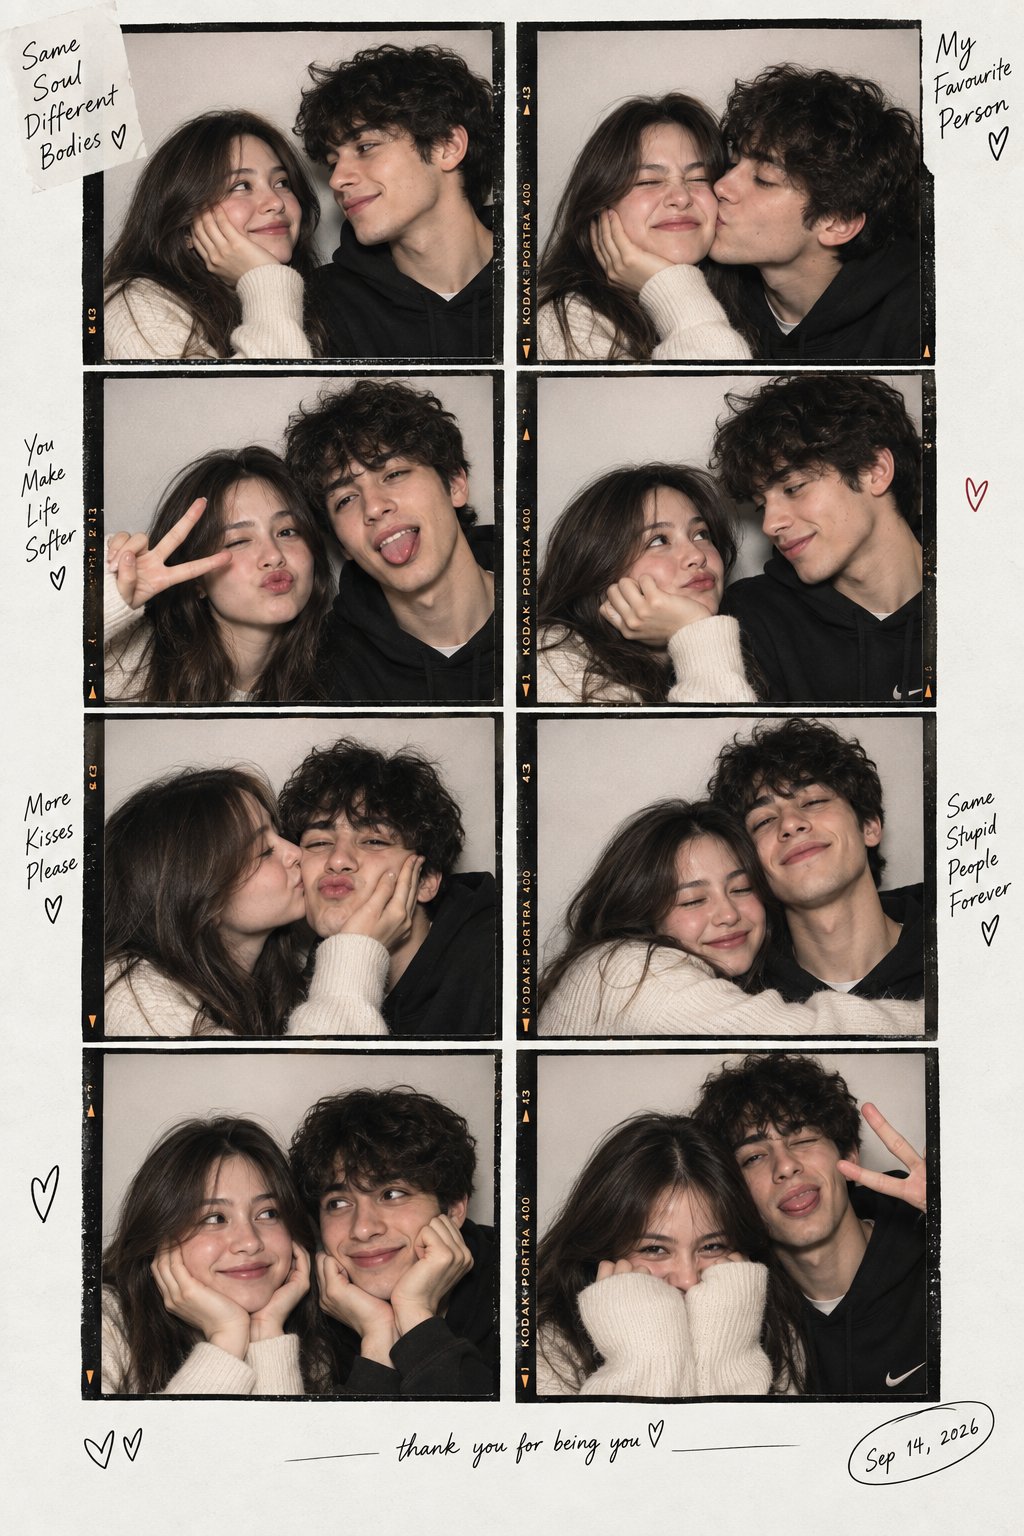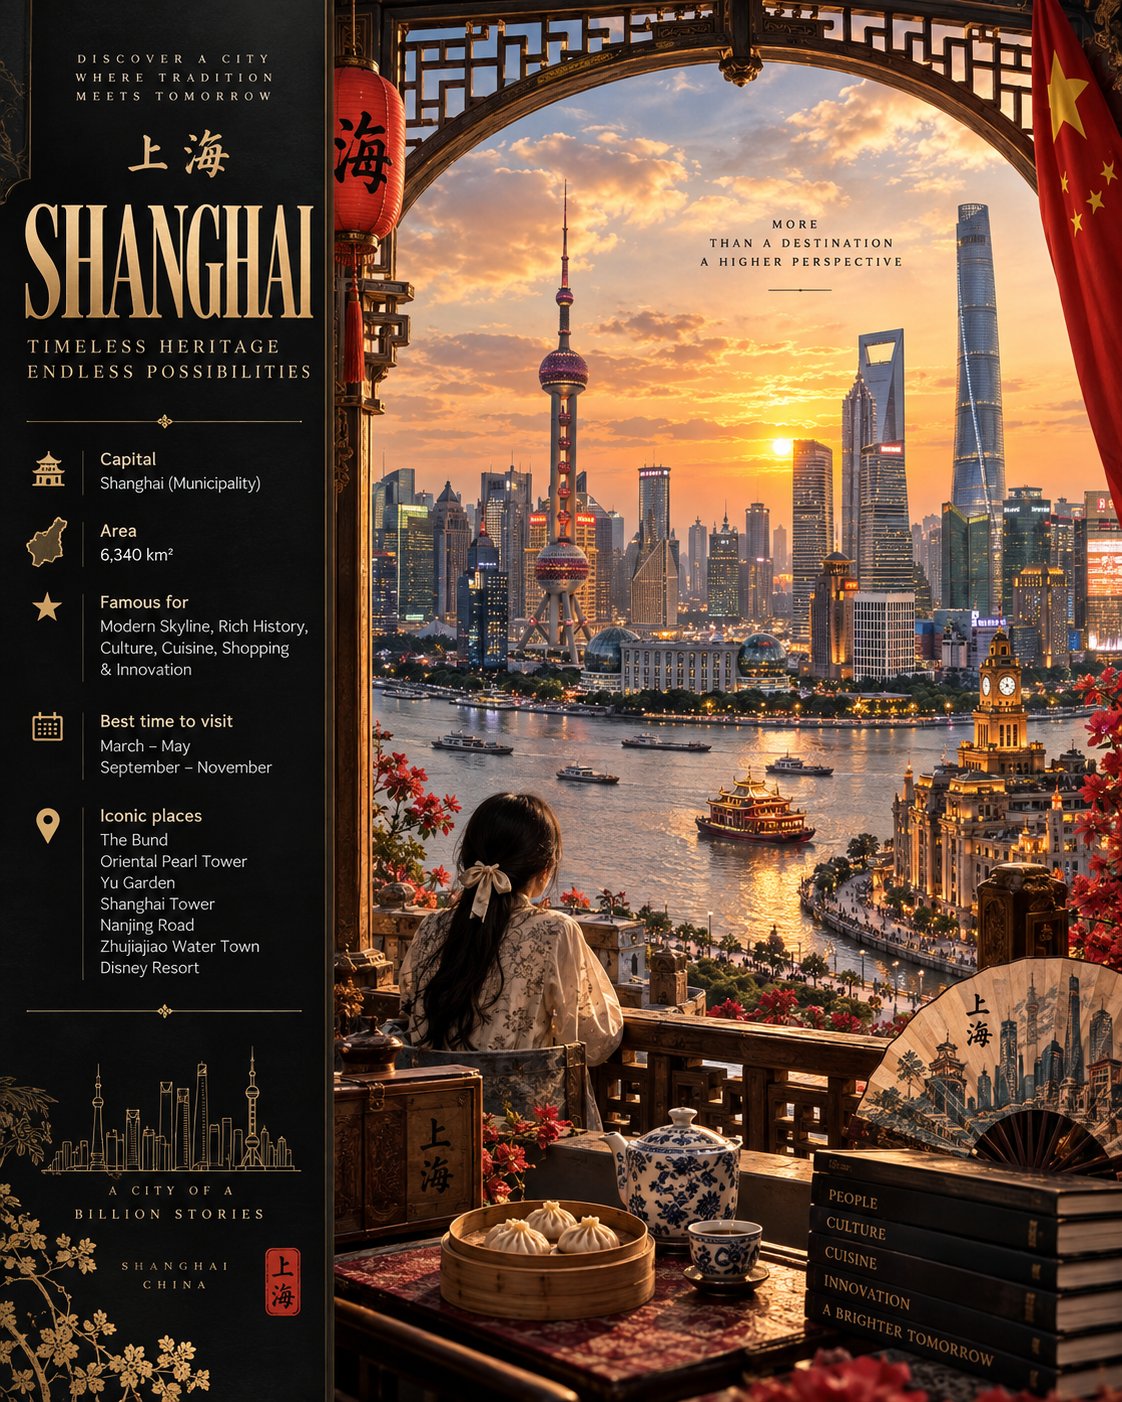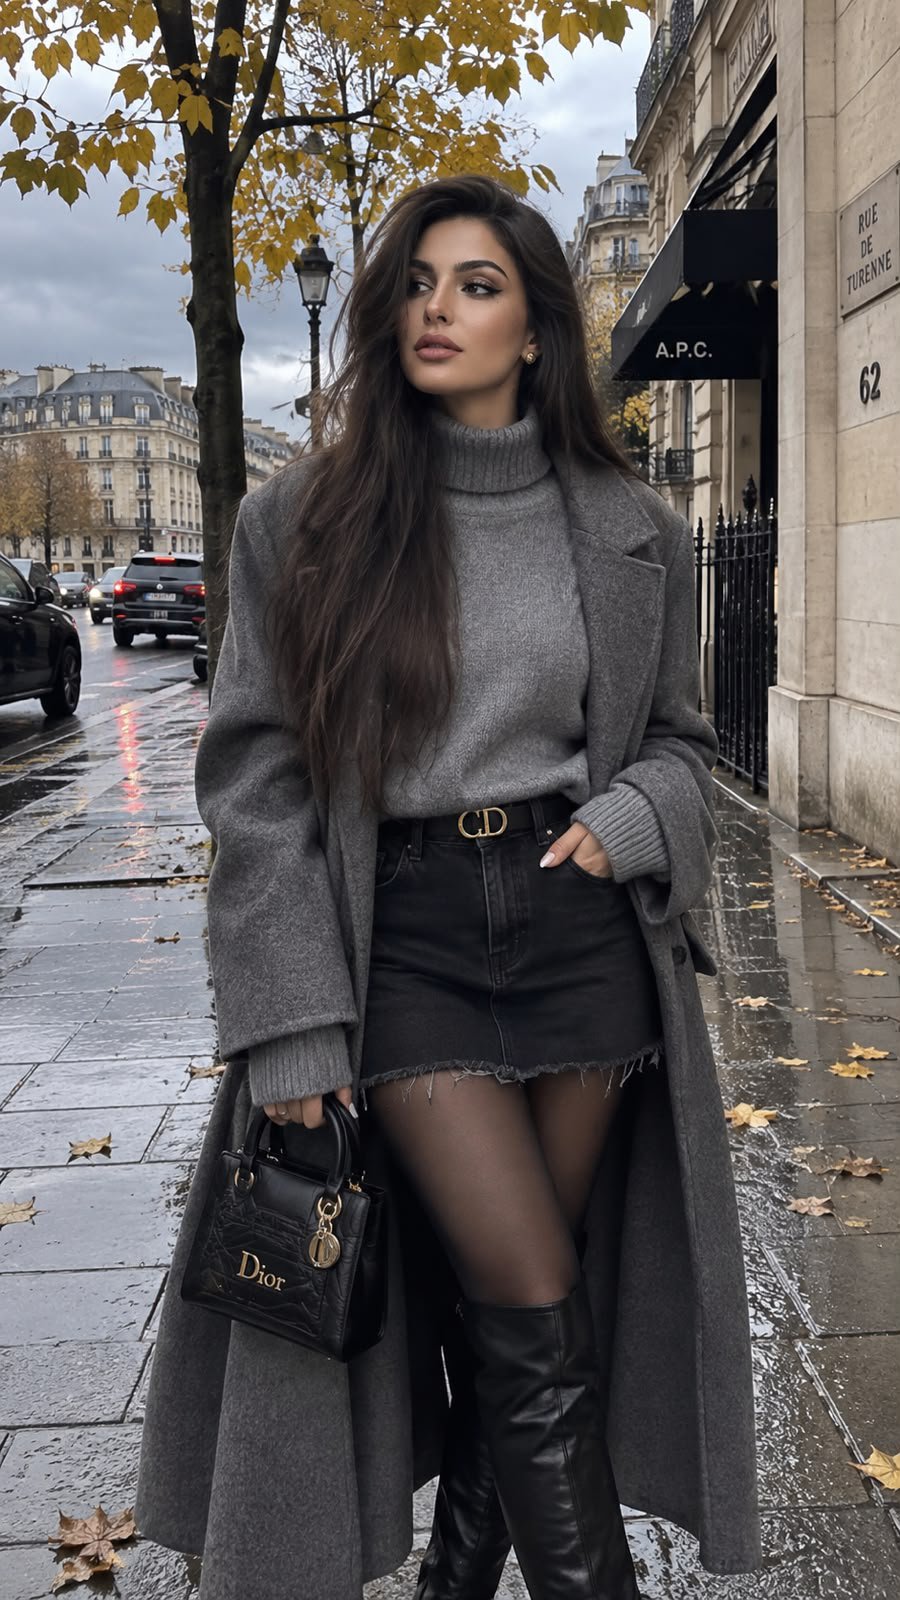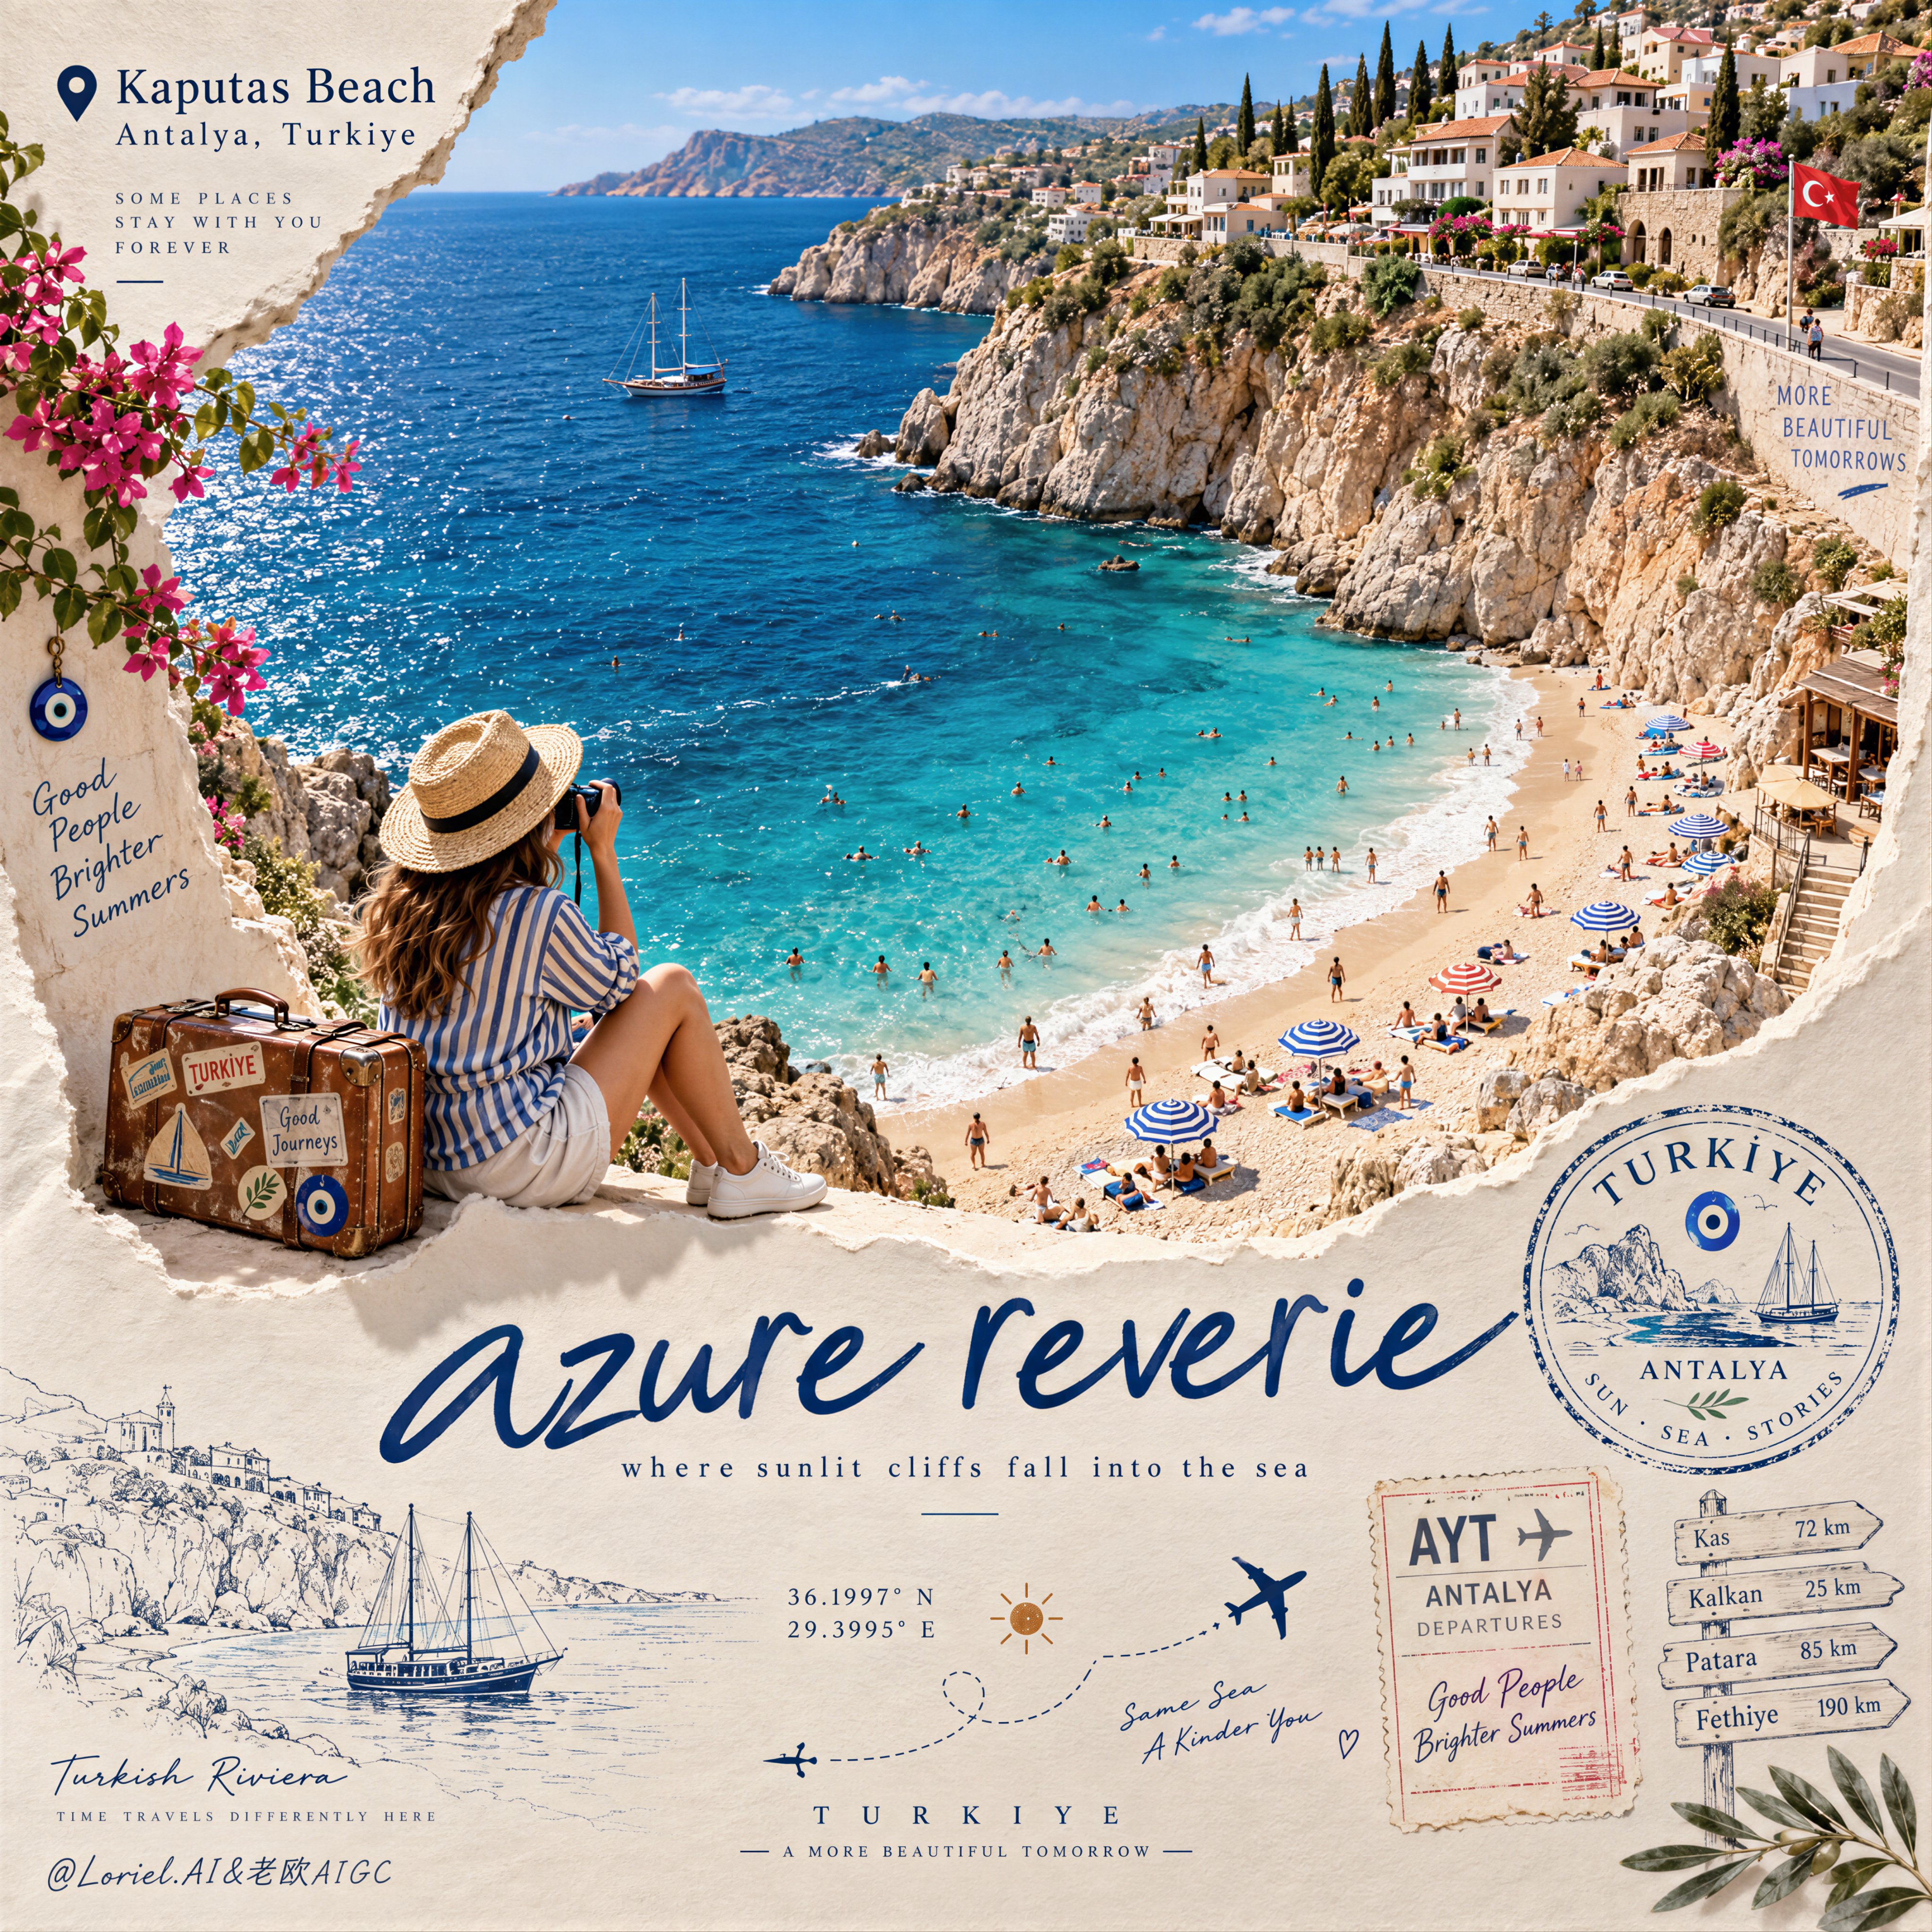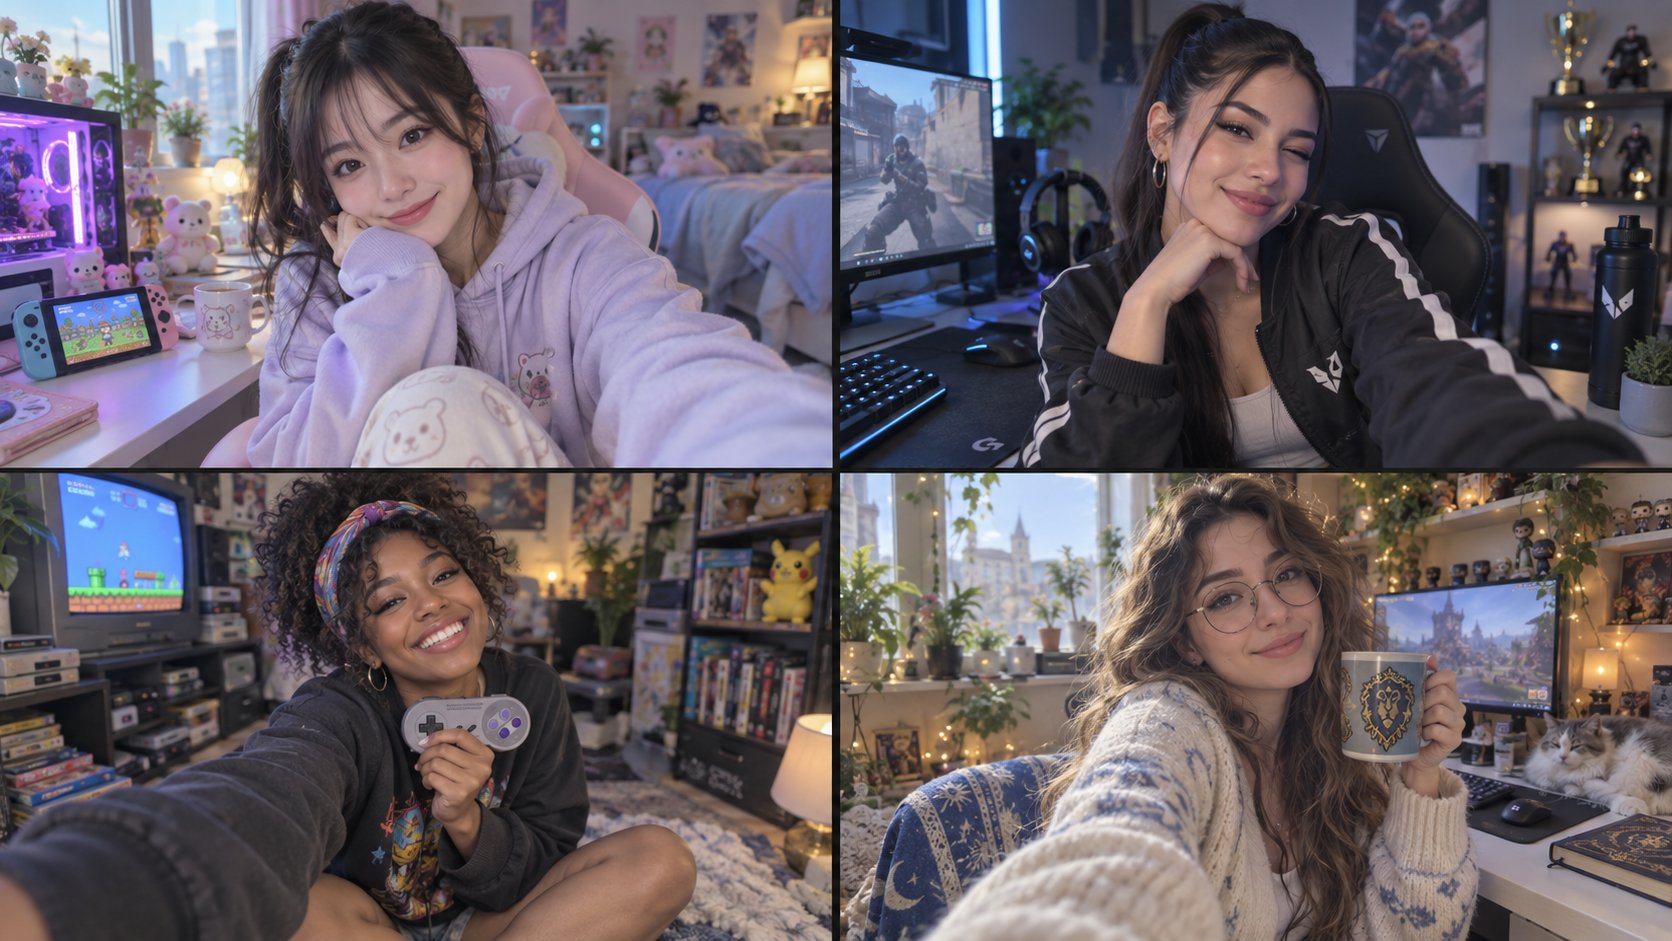
Female Gaming Influencer 2x2 Grid
 GPT Image 2.5OpenAIimage
2x2 grid, 16:9, do this for 4 female gaming influencers with poses that steal your heart. // FN: influencer_frame(SUBJECT, SETTING, TIME, RIG, PLATFORM, INTENT) // Edit INPUT only. Everything below derives. INPUT SUBJECT = " $ subject" SETTING = "Ai infers" TIME = "Ai infers" RIG = SELF // SELF | FRIEND | TRIPOD | MIRROR | DRONE PLATFORM = IG_FEED // IG_FEED | IG_STORY | TIKTOK | PINTEREST INTENT = "candid morning" INFER :: RIG → geometry, gaze, and what the fiction is SELF → 23mm front, 45–60cm, face widened ~8%, lens ABOVE eye level, chin foreshortened, gaze INTO lens, one arm's angle implied by crop FRIEND → 26mm rear, 1.5–3m, correct proportion, eye level, gaze into lens, full body possible, environment legible TRIPOD → 26mm, 2–4m, gaze deliberately AWAY (the candid fiction), body squared to a mark on the ground, static pose held for a burst MIRROR → phone IN FRAME, screen glow on face/hands, gaze at reflection NOT lens, room reversed, fingerprints on the glass DRONE → 24mm from above, subject small, the LOCATION is the subject INFER :: SETTING + TIME → light class → computational behavior interior_backlit → HDR stack: window keeps detail, never clips; edge halo golden_hour → warm, long shadows, veiling flare, lifted blacks overcast → flat, cool, low contrast, no shadow direction night_artificial → night mode: multi-second stack ⇒ anything that moved ghosts; shadows unnaturally lit; grain scrubbed to plastic harsh_noon → HDR fights it: raccoon shadows lifted, skin looks flat INFER :: PLATFORM → container IG_FEED = 4:5, 1080px ceiling, mild re-encode IG_STORY = 9:16, safe zones top/bottom kept empty TIKTOK = 9:16, heavier compression, saturation pushed PINTEREST= 2:3, text overlay space reserved DERIVE :: always, regardless of input D1 synthetic depth ⇒ mask errors mandatory: one hair-gap filled with blur, a ~2px halo at the shoulder, blur bucketed by depth not continuous D2 beauty pass ⇒ cheeks poreless WHILE lashes/brows stay razor sharp D3 grade ⇒ blacks lifted to ~12/255 with cyan bias, nothing pure black D4 INTENT ⇒ props staged: labels rotated to camera, food untouched, "unnoticed" objects squared to the table edge FORBIDDEN ✗ true optical bokeh falloff ✗ clipped white window ✗ uniform skin sharpness ✗ pure black ✗ DSLR micro-detail at 1080 ✗ genuine unawareness of the camera RENDER // resolve every {slot}, emit prose only {PLATFORM.aspect} phone photo. {SUBJECT} at {SETTING}, {TIME}. {RIG.geometry_prose}. {light_class.prose}. Background blurred the artificial way phones do it, with {D1}. {D2}. {D3}. {D4}. Slightly soft at 1080px. AUDIT window_luma_max 8/255 · gaze matches RIG
Details
- Type
- AI Image Prompts
- Aspect Ratio
- 1672:941
- Updated
- Sep 21, 2026
How to use this prompt
- 1Copy the full prompt with the copy button above.
- 2Open GPT Image 2.5 by OpenAI, or any image generator with a similar style range.
- 3Paste the prompt, then swap the subject and style keywords to match your idea.
- 4Match the example's settings (1672:941 · Cinematic · Fashion · Portrait), then iterate — small wording changes shift the output a lot.
Frequently asked questions
Which AI model generated this image?
This image was generated with GPT Image 2.5 by OpenAI. The prompt on this page is the exact text used to create it.
What settings does this prompt use?
The example was generated with GPT Image 2.5 using: 1672:941 · Cinematic · Fashion · Portrait. Reusing these settings gives the closest match.
How do I get similar results?
Copy the prompt as-is first, then replace only the subject while keeping the style, lighting, and composition keywords. Generate a few variations — outputs differ between runs.
Can I modify this prompt?
Yes. Prompts work best as starting points — adjust descriptors, aspect ratio, or style tags to make the output your own.